Crawled – Currently Not Indexed: Why It Happens & How to Fix It
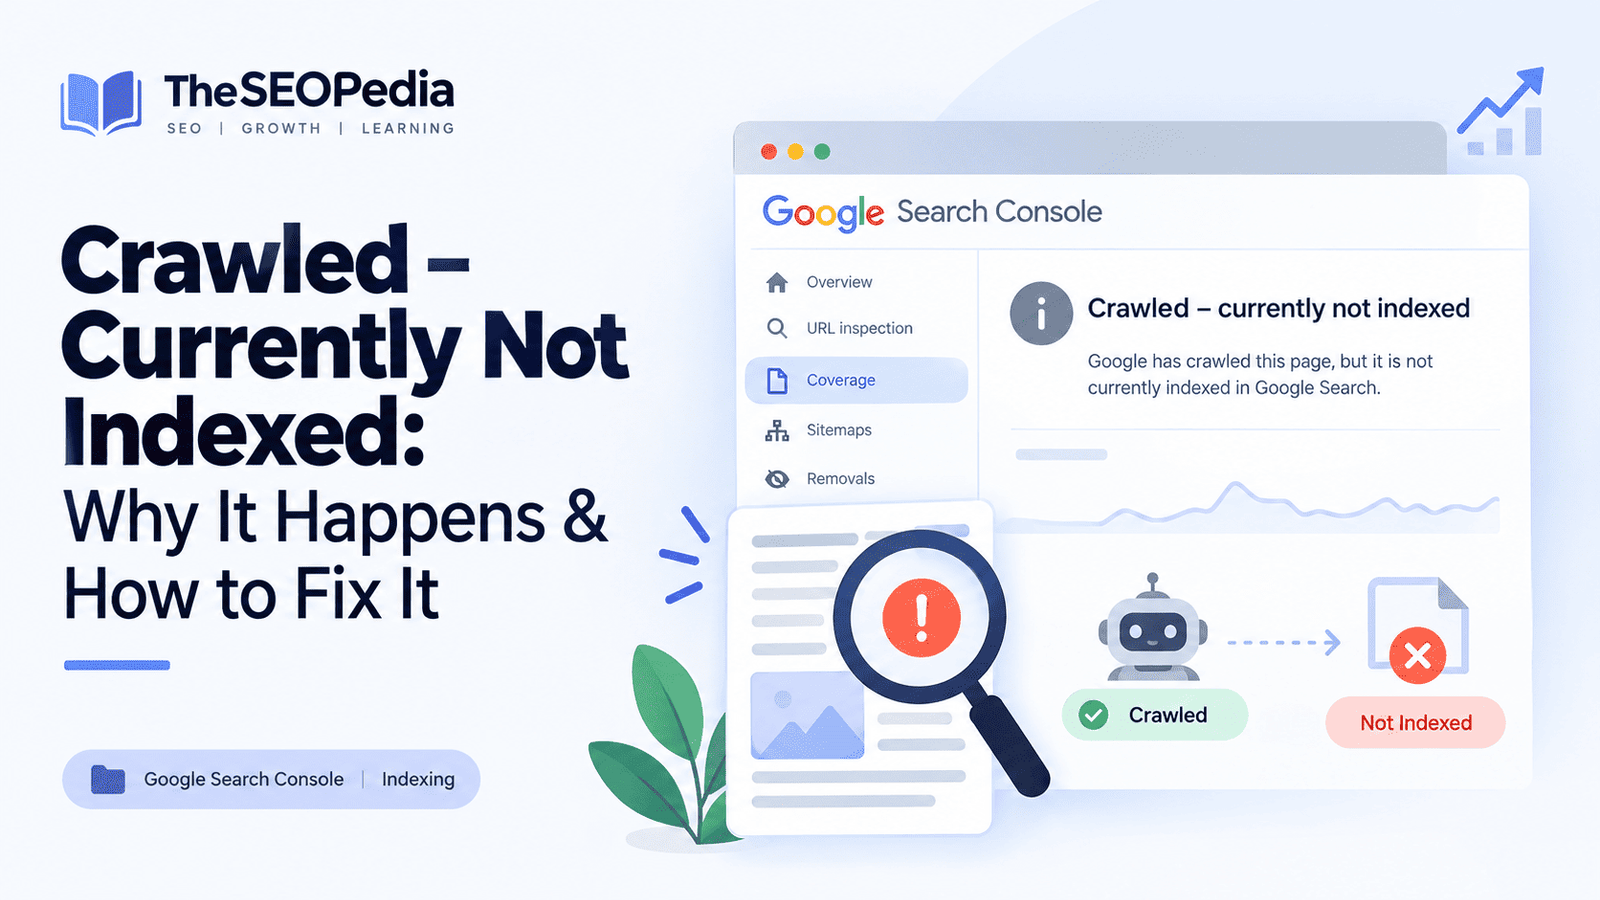
Seeing “Crawled – currently not indexed” in Google Search Console means Google has crawled your page but has not added it to Google’s search index yet.
It does not automatically mean your website has a technical SEO error or Google penalty. Google says the page may or may not be indexed in the future, and there is no need to repeatedly resubmit the URL for crawling.
The most effective approach is to first determine why the page is not being indexed, then improve the specific problem-such as thin or redundant content, duplicate URLs, canonicalization issues, weak internal linking, or content that does not provide enough unique value.
If you’re troubleshooting a broader technical SEO problem, our technical SEO guide is a useful place to start.
Quick Answer
“Crawled – currently not indexed” means Google successfully accessed and crawled your URL, but has not included it in the Google Search index at this time.
To address the issue:
- Check the URL in Google Search Console’s URL Inspection tool.
- Make sure the page is technically eligible for indexing.
- Check the canonical URL and duplicate versions of the page.
- Improve thin, repetitive, or unhelpful content.
- Make the page’s search intent and purpose clear.
- Add relevant internal links from important pages.
- Make sure Google can access and render the important content.
- Include the URL in your XML sitemap when appropriate.
- After making meaningful improvements, request indexing for important URLs.
- Monitor the Page Indexing report rather than repeatedly submitting the same URL.
Google does not guarantee that a particular page will be crawled, indexed, or shown in search, even when the page follows Google’s Search Essentials.
What Does “Crawled – Currently Not Indexed” Mean?
Google Search works through several stages.
Crawling is when Google discovers and fetches a URL.
Indexing is when Google processes the page and decides whether and how it should be stored in its Search index.
Serving is when Google uses its index to return relevant pages for a user’s search.
Therefore:
Crawled ≠ Indexed ≠ Ranked
A page can be successfully crawled without being indexed.
Google’s Page Indexing report specifically describes “Crawled – currently not indexed” as a page that was crawled by Google but is currently not indexed. Google also notes that the page may be indexed in the future.
If you want to understand the crawling side in more detail, see our guide on how to perform technical website crawls.
Is “Crawled – Currently Not Indexed” an Error?
Not necessarily.
This distinction is important.
The status itself doesn’t tell you that your server is broken, your robots.txt is blocking Google, or your website has received a penalty.
Instead, it tells you the URL has already been crawled but isn’t currently in Google’s index.
That means your first question should not be:
“How do I force Google to index this page?”
It should be:
“Why isn’t this page providing enough reason to be indexed, or is there an indexing signal I need to fix?”
Crawled vs. Discovered – Currently Not Indexed
These two Google Search Console statuses are easy to confuse.
| Status | What it means |
|---|---|
| Crawled – currently not indexed | Google crawled the URL but has not indexed it |
| Discovered – currently not indexed | Google knows about the URL but has not crawled it yet |
If you’re dealing with the second status, see our dedicated guide:
Discovered – Currently Not Indexed: 8 Steps to Fix It
The distinction matters because the troubleshooting process is different.
With Discovered – currently not indexed, you investigate discovery and crawling.
With Crawled – currently not indexed, Google has already fetched the page, so you should pay closer attention to the page itself, its uniqueness, canonicalization, rendering, internal links, and overall usefulness.
Why Is My Page Crawled but Not Indexed?
There isn’t one universal reason.
Google evaluates pages automatically and does not provide a specific “your page failed because of X” explanation for every URL.
However, several patterns are worth investigating.
1. The Content Is Too Thin
A page may technically contain text but still provide little useful information.
For example, imagine a page targeting:
What is technical SEO?
If the article contains only a short definition that is almost identical to hundreds of other pages, there may be little unique value for a searcher.
Instead, a useful page could explain:
- What technical SEO means
- Why it matters
- Common technical SEO problems
- How to identify those problems
- Examples
- Recommended tools
- How to fix common issues
- Frequently asked questions
The goal isn’t to make every article extremely long.
The goal is to make the page useful and sufficiently complete for its intended purpose.
For a broader look at technical SEO, see What Is Technical SEO?.
2. Your Page Is Too Similar to Another Page
Duplicate and near-duplicate content can create indexing problems.
For example, suppose your website has:
/seo-audit//website-seo-audit//free-seo-audit//seo-audit-tool/
If these pages provide almost the same information and target essentially the same intent, Google may have difficulty determining which URL should represent that content.
What to do
Compare the affected page with:
- Other pages on your website
- Similar URLs
- Category pages
- Tag pages
- Parameter URLs
- Printer-friendly URLs
- Alternative versions of the same content
If two pages genuinely serve the same purpose, consider whether you should:
- Consolidate them
- Redirect one to the other
- Improve their differentiation
- Use appropriate canonicalization
- Remove unnecessary versions
Don’t create multiple pages simply because you found slightly different keyword variations.
If your site has many unnecessary or redundant URLs, our guide to index bloat and how to fix it can help you identify the wider problem.
3. The Page Doesn’t Match Search Intent Well
Suppose someone searches:
how to check backlinks
They probably want a practical process.
If your page spends most of its 2,000 words explaining the history of backlinks and only provides a vague definition, it may not satisfy the search intent particularly well.
Before publishing or revising a page, ask:
What does someone actually want when they search this keyword?
Then structure the page around that need.
For a troubleshooting keyword, provide troubleshooting.
For a definition keyword, provide a clear definition first.
For a comparison query, provide a comparison.
For a “how to” query, provide actionable steps.
4. The Page Doesn’t Add Enough Unique Information
Creating another article that simply rephrases existing information isn’t a strong content strategy.
For example, if dozens of pages already explain:
“SEO means Search Engine Optimization.”
creating another 500-word article saying essentially the same thing doesn’t give readers much additional value.
Instead, add something useful:
- Original examples
- Screenshots
- Data
- First-hand observations
- Step-by-step instructions
- Expert commentary
- Comparisons
- Templates
- Checklists
- Calculations
- Case studies
- Common mistakes
- Troubleshooting information
Your goal should be:
Make the page the most useful answer for its intended query—not simply the longest answer.
5. Weak Internal Linking
Internal links help Google discover and understand relationships between pages.
Suppose you publish:
Crawled – Currently Not Indexed: How to Fix It
but the page has no meaningful internal links pointing to it.
That’s weaker than a page that is naturally connected to:
- Google Search Console
- Google indexing
- Technical SEO
- Sitemap guides
- Crawling guides
- Canonical URL guides
- Search Console error guides
A better internal-link structure
Your article could receive links from:
Technical SEO Guide
→ Crawled – Currently Not Indexed
Google Indexing Guide
→ Crawled – Currently Not Indexed
Website Crawl Guide
→ Crawled – Currently Not Indexed
Index Bloat Guide
→ Crawled – Currently Not Indexed
This creates a clear topical relationship.
For a practical example of technical crawling, read How to Perform Technical Website Crawls for SEO.
You can also learn more about how crawl demand and site size relate in Crawl Budget for SEO.
6. Google Can’t Properly Access or Render Important Content
Although “Crawled – currently not indexed” means Google has crawled the URL, you should still check whether Google can properly process the page.
Check:
- HTTP status
- robots.txt
- noindex directives
- canonical tag
- JavaScript rendering
- important content in the rendered HTML
- mobile version
- server responses
- redirects
Don’t assume that because Googlebot fetched the URL, everything on the page was processed exactly as you intended.
For a broader technical checklist, see What Is Technical SEO?.
7. The Canonical URL Is Different
Canonicalization tells search engines which URL should represent a piece of content when multiple URLs are substantially similar.
Check the URL Inspection report for the affected page and compare:
User-declared canonical
with
Google-selected canonical
If Google selects a different URL, investigate why.
Possible causes include:
- Duplicate content
- Similar pages
- Multiple URL versions
- Incorrect canonical tags
- Internal linking pointing primarily to another URL
- HTTP/HTTPS inconsistencies
- www/non-www versions
- URL parameters
Don’t blindly change canonical tags just because a page isn’t indexed.
First determine whether the alternate canonical is actually the correct page.
This is especially important for websites with filters and multiple URL variations. Our guide to faceted navigation and SEO best practices covers duplicate URLs, canonicalization, crawl budget, and indexing issues in more detail.
8. The Page Is New
A newly published page may not be indexed immediately.
Google’s documentation says crawling can take anywhere from a few days to a few weeks, and requesting a crawl does not guarantee immediate inclusion in Search.
Therefore, if you published the page yesterday and it appears under “Crawled – currently not indexed,” don’t immediately rebuild the entire article.
Give Google time to process the page.
9. The Page May Not Need to Be Indexed
This is an important point that many SEO guides overlook.
Not every URL on your website needs to appear in Google’s index.
Examples can include:
- Certain filtered URLs
- Duplicate pages
- Internal search results
- Parameter variations
- Thin utility pages
- Alternative versions of content
If a URL has no useful search purpose, forcing it into Google’s index may not be the right objective.
The better question is:
Should this URL exist as a standalone search result at all?
If the answer is no, consolidation, canonicalization, or another appropriate technical solution may be better than trying to get it indexed.
How to Fix “Crawled – Currently Not Indexed”
Use this process rather than repeatedly pressing Request Indexing.
Step 1: Inspect the URL
Open:
Google Search Console → URL Inspection
Enter the affected URL.
Look at:
- Indexing status
- Crawled page
- User-declared canonical
- Google-selected canonical
- Last crawl
- Page resources
- Mobile usability or relevant page experience information
- Any detected issues
Google provides the URL Inspection tool specifically for understanding how Google sees individual URLs.
Step 2: Confirm the Page Should Be Indexed
Ask:
- Is this an important page?
- Does it target a real search intent?
- Does it provide unique value?
- Is it substantially different from other pages?
- Would users benefit from finding it through Google?
If the answer is no, don’t force indexing.
Step 3: Check for noindex
Check the page’s robots meta directives and HTTP headers.
You don’t want an intentional noindex directive on a page you expect Google to index.
Also check whether your CMS or SEO plugin has accidentally added one.
Step 4: Check the Canonical
Make sure the canonical URL points to the correct version of the page.
If Google has selected another canonical URL, investigate the reason instead of simply overriding it.
Step 5: Improve the Content
This is often the most important step.
Look at the page from a user’s perspective.
Ask:
If I were searching for this topic, what information would I still need after reading this article?
Then add the missing information.
Consider adding:
- Clear definitions
- Step-by-step instructions
- Examples
- Screenshots
- Original analysis
- Tables
- FAQs
- Common mistakes
- Troubleshooting
- Relevant statistics
- Expert explanations
Step 6: Improve Internal Links
Add relevant internal links from pages that are already established on your website.
For example, if you’re trying to index an article about Google indexing, link to it from related articles about:
- Google Search Console
- Technical SEO
- XML sitemaps
- Crawling
- Indexing
- SEO audits
Use natural anchor text.
Don’t add dozens of forced exact-match links.
A strong internal-linking cluster for this topic could include:
- What Is Technical SEO?
- How to Perform Technical Website Crawls for SEO
- Crawl Budget for SEO
- What Is Index Bloat and How to Fix It?
- Discovered – Currently Not Indexed: How to Fix It
- Faceted Navigation: Meaning, Issues and SEO Best Practices
These links connect closely related concepts instead of creating a random list of internal links.
Step 7: Check Your Sitemap
Make sure your important canonical URLs are included in your XML sitemap.
A sitemap isn’t a guarantee that Google will index a page.
Think of it primarily as a discovery signal.
Your SEO Plan Template also covers crawling, indexing, XML sitemaps, robots.txt, and other technical SEO elements as part of a broader SEO strategy.
Step 8: Request Indexing After Making Real Changes
Once you’ve made meaningful improvements, you can use:
Google Search Console → URL Inspection → Request Indexing
But don’t repeatedly submit the same unchanged URL.
Google explicitly says that repeatedly requesting a recrawl won’t make Google crawl the URL faster, and that requesting a crawl doesn’t guarantee inclusion in Search.
The correct sequence is:
Diagnose → Improve → Request indexing → Wait → Monitor
Not:
Request indexing → Request indexing → Request indexing
How Long Does “Crawled – Currently Not Indexed” Take to Fix?
There is no guaranteed timeframe.
Google says crawling can take anywhere from a few days to a few weeks, and indexing isn’t guaranteed.
A page might eventually become indexed without intervention.
However, if an important page remains unindexed for a long time, investigate it rather than assuming Google simply needs more time.
Look for patterns across your website.
For example:
One page affected
→ Investigate that page.
Hundreds of similar pages affected
→ Investigate site architecture, duplication, templates, content quality, canonicalization, and other site-wide patterns.
If you discover hundreds or thousands of low-value URLs, investigate whether your site has an index bloat problem rather than treating every excluded URL individually.
Should You Keep Requesting Indexing?
No.
Requesting indexing can be useful after you have created or substantially updated an important page, but repeatedly submitting the same URL isn’t a solution.
If Google has already crawled your page, focus on understanding why it hasn’t been indexed.
Does “Crawled – Currently Not Indexed” Mean a Google Penalty?
No, the status itself does not mean you have received a Google penalty.
It simply means Google crawled the URL but currently hasn’t included it in the index.
Don’t confuse indexing status with a manual action.
If you’re concerned about penalties, check the appropriate reports in Google Search Console separately.
Does Crawled – Currently Not Indexed Affect SEO?
The status itself isn’t a ranking penalty.
However, an unindexed page generally cannot receive organic search traffic in the same way an indexed page can because Google isn’t currently using that URL as an indexed search result.
The practical problem is therefore:
You created a page that you want people to find, but Google hasn’t currently included it in its index.
The solution is to determine why and decide whether the page should be improved, consolidated, or left out of the index.
Crawled vs. Indexed vs. Ranked
These concepts are worth keeping separate.
Crawled
Google has fetched the page.
Indexed
Google has processed the page and included it in its Search index.
Ranked
Google has selected the page as a candidate for a particular search query and assigned it a position relative to other results.
Therefore, getting a page crawled doesn’t guarantee that it will be indexed.
Getting a page indexed doesn’t guarantee that it will rank highly.
And ranking highly for one keyword doesn’t guarantee rankings for every related keyword.
A Practical Checklist
If your page says “Crawled – currently not indexed,” run through this checklist:
- Is the page worth indexing?
- Does it satisfy a clear search intent?
- Is the content genuinely useful?
- Does it contain unique information?
- Is it substantially different from similar pages?
- Is the page free from accidental
noindexdirectives? - Is the canonical URL correct?
- Does Google select the expected canonical?
- Does the page return a normal HTTP response?
- Can Google access the important content?
- Does the rendered page contain the important content?
- Are there relevant internal links pointing to it?
- Is the canonical URL included in the sitemap?
- Have you fixed the underlying issue before requesting indexing?
- Have you given Google enough time to recrawl and process the page?
Final Takeaway
“Crawled – currently not indexed” isn’t a button you need to press your way out of.
Google has already crawled the page.
Your job is to determine whether the URL:
- Should be indexed
- Is technically eligible
- Provides enough unique value
- Matches the searcher’s intent
- Is sufficiently differentiated from other URLs
- Has the right canonical
- Is properly connected through your site’s internal linking structure
Then make the necessary improvements and request indexing if the URL is important.
Most importantly, don’t judge your entire website based on the number of URLs in this report. A large “Crawled – currently not indexed” count isn’t automatically a disaster. What matters is understanding which URLs are important, why they’re being excluded, and whether those URLs genuinely deserve a place in Google’s index.
For important pages, focus on usefulness, uniqueness, clear intent, technical accessibility, and strong site architecture rather than trying to force Google to index every URL.
FAQ: Crawled – Currently Not Indexed
What does “Crawled – currently not indexed” mean?
It means Google crawled your page but has not currently included it in its Search index. Google says the page may be indexed later.
How do I fix “Crawled – currently not indexed”?
Start by inspecting the URL in Google Search Console. Check indexability, canonicalization, duplication, rendering, content quality, search intent, internal links, and sitemap inclusion. Then make meaningful improvements and request indexing for important URLs.
Is “Crawled – currently not indexed” a Google penalty?
No. The status itself does not mean your website has received a penalty. It simply describes the current indexing state of the URL.
Should I request indexing again?
You can request indexing after making meaningful changes, but repeatedly requesting indexing for an unchanged URL isn’t an effective fix.
How long does Google take to index a crawled page?
There is no guaranteed timeframe. Google says crawling can take from a few days to a few weeks, and crawling or requesting indexing does not guarantee that a page will be included in Search.
What is the difference between “Crawled – currently not indexed” and “Discovered – currently not indexed”?
With Crawled – currently not indexed, Google has already crawled the URL but hasn’t indexed it.
With Discovered – currently not indexed, Google knows about the URL but hasn’t crawled it yet.
For the latter issue, see our complete guide to Discovered – Currently Not Indexed.
Can thin content cause a page to remain unindexed?
Thin or low-value content can be one reason to investigate, particularly when a page provides little unique information compared with other pages. However, the Search Console status alone doesn’t identify thin content as the specific cause for an individual URL.
Can duplicate content cause “Crawled – currently not indexed”?
Duplicate or substantially similar pages are worth investigating. Google analyzes duplicate content and canonical URLs when processing pages for its index.
Does adding a page to an XML sitemap guarantee indexing?
No. A sitemap helps Google discover URLs, but it doesn’t guarantee that Google will index or rank them.
